Audio-Visual Speech Enhancement in Complex Scenarios with Separation and Dereverbration Joint Modeling
The following table presents, for each evaluation sentence, four separated utterances generated by the Separation only, Sep before Derev, Separation only(joint), and Sep before Derev(joint), respectively. The model weights and inference code are available at https://github.com/JarenDD/AVSE-4.
Demo examples from the test set
| Demo | 1 | 2 | 3 |
| Mixtur | 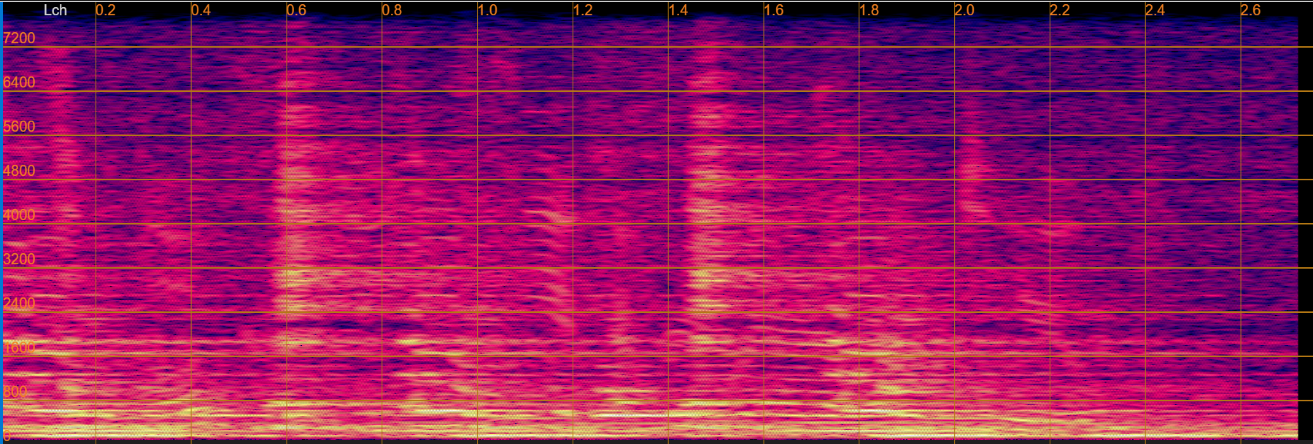 |
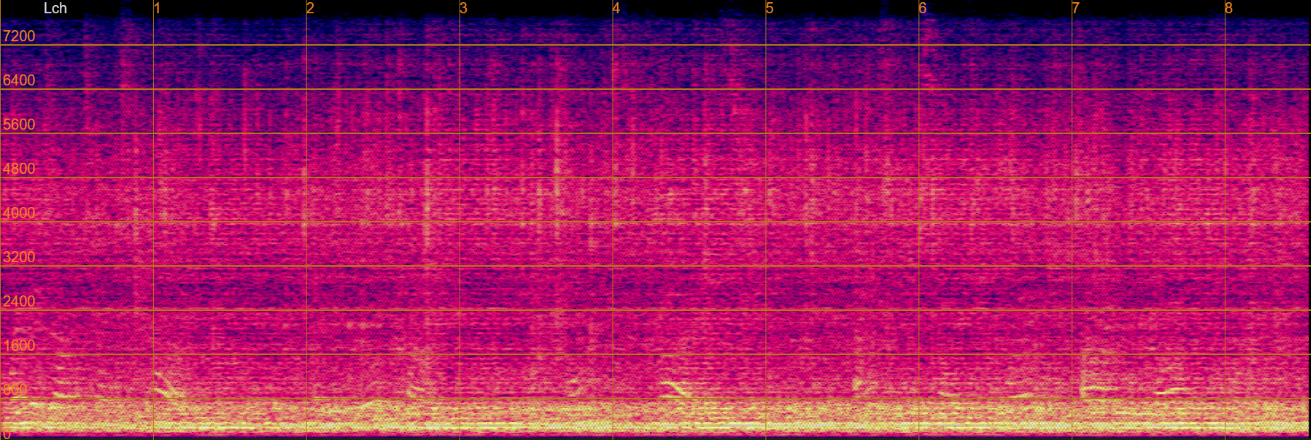 |
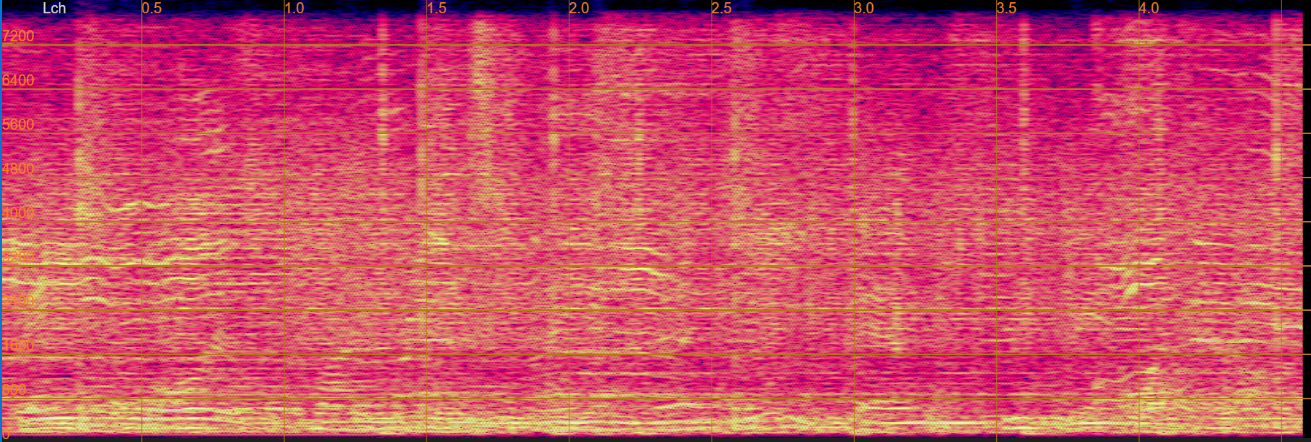 |
| (Audio) | |||
| Target | 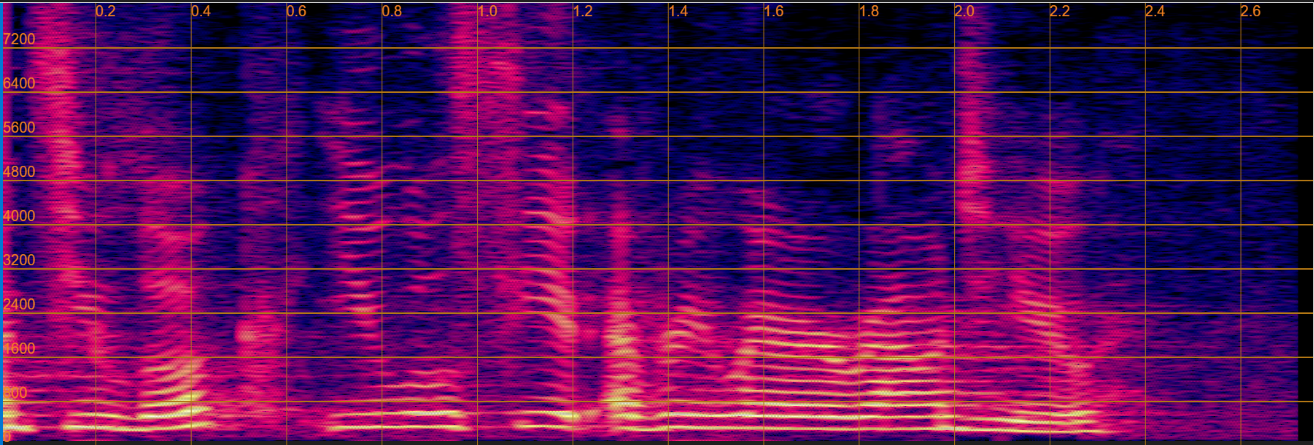 |
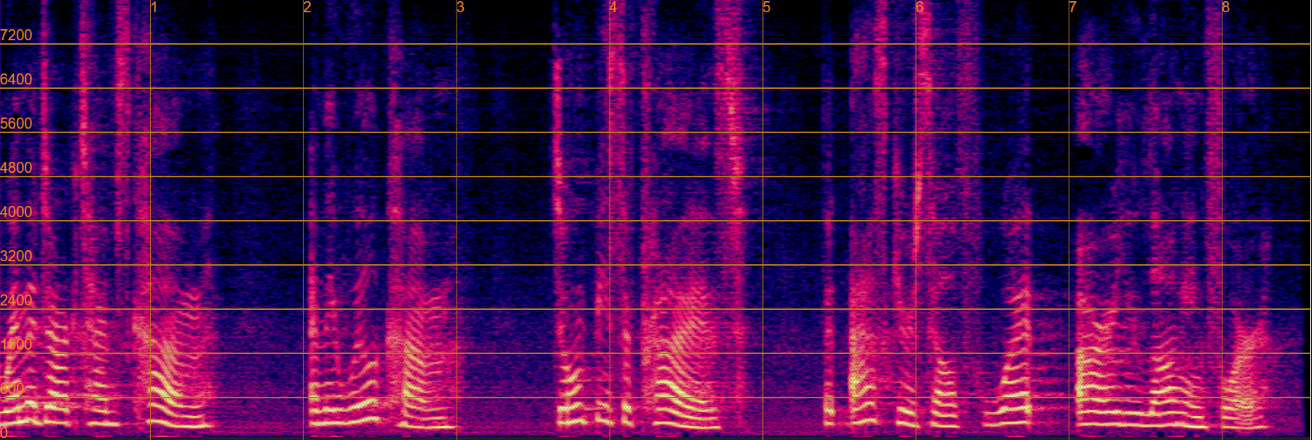 |
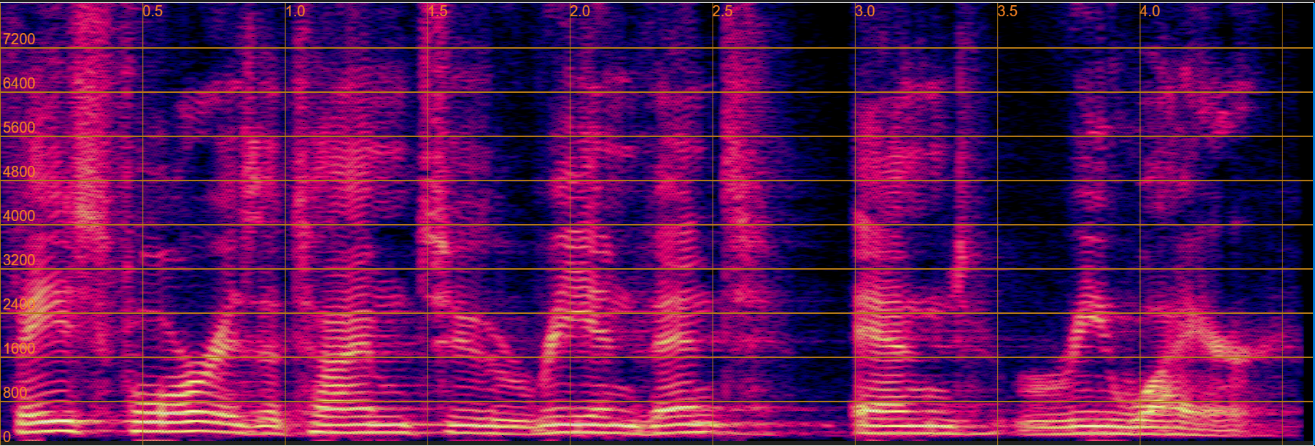 |
| (Audio) | |||
| Separation only | 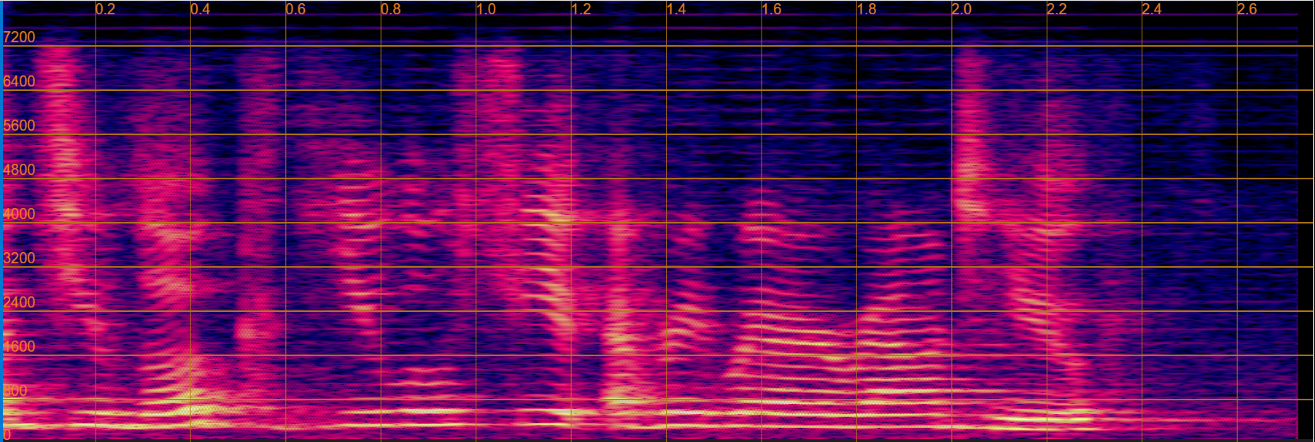 |
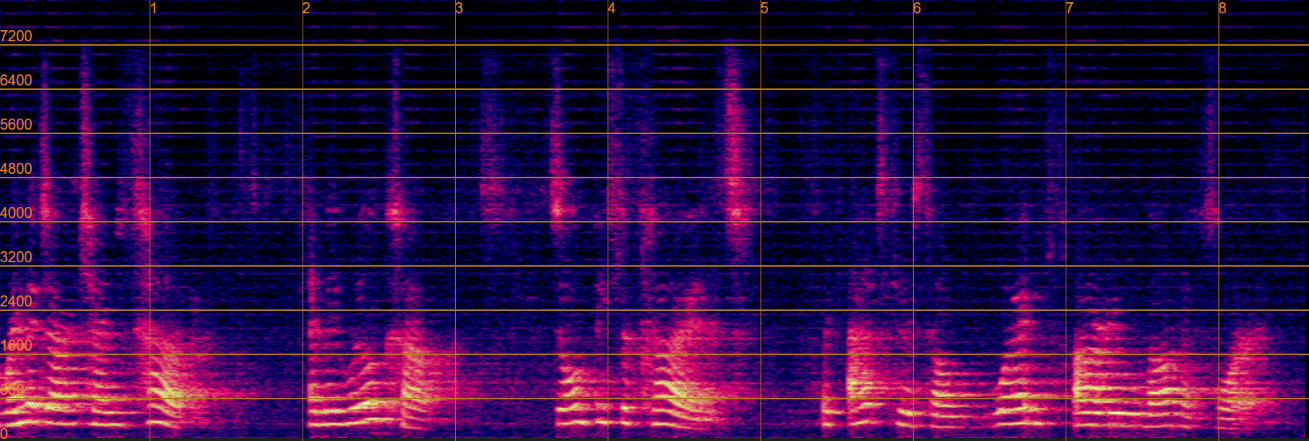 |
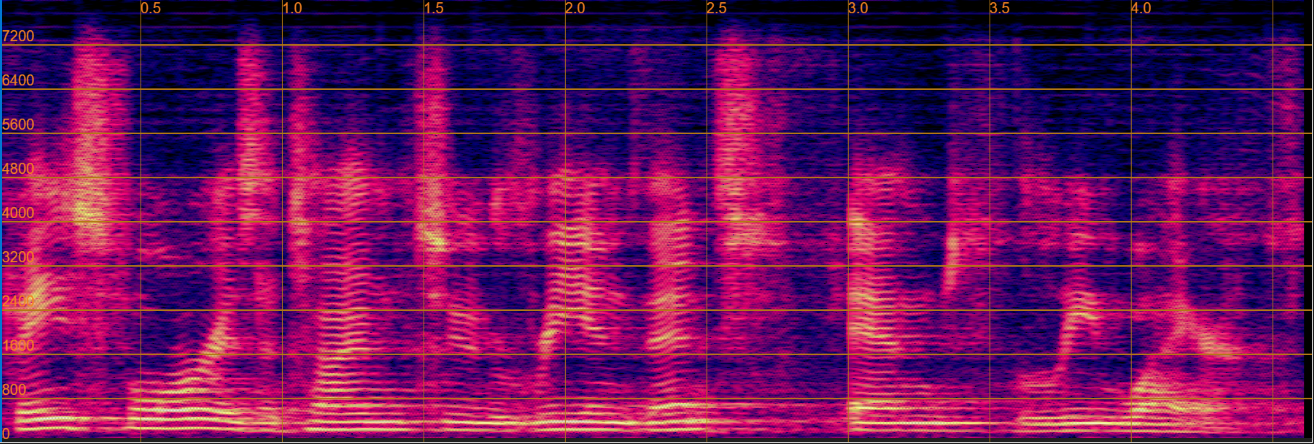 |
| (Audio) | |||
| Sep before Derev | 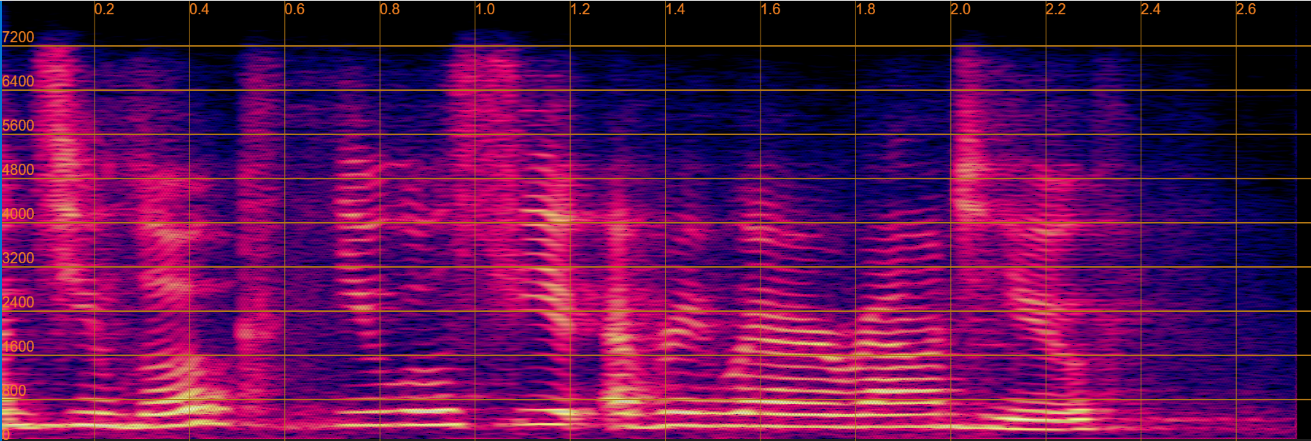 |
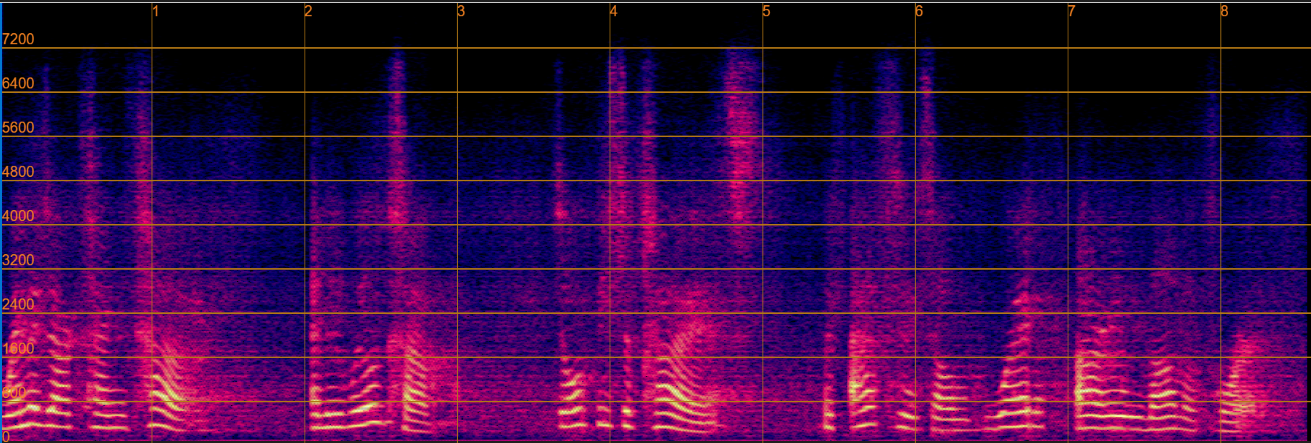 |
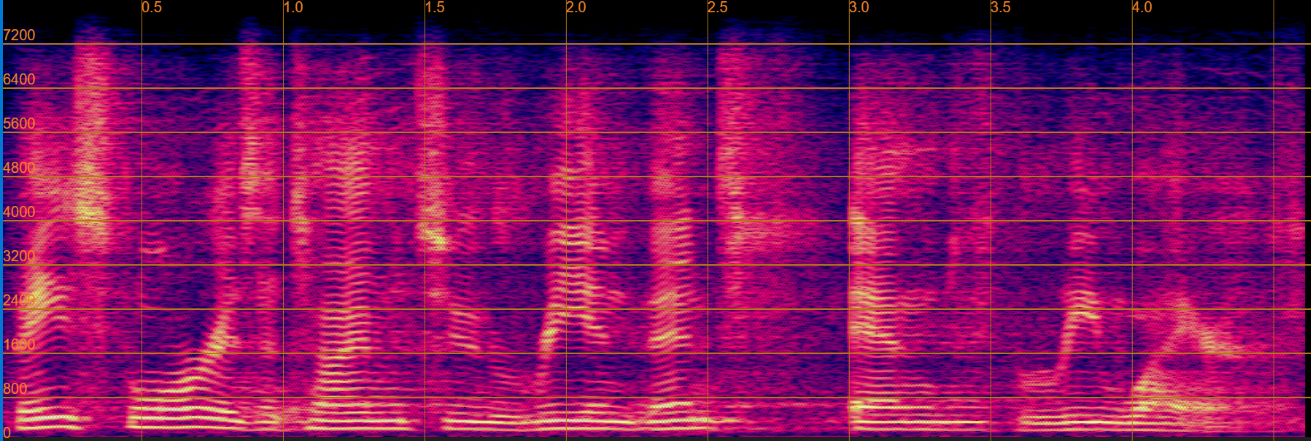 |
| (Audio) | |||
| Separation only(joint) | 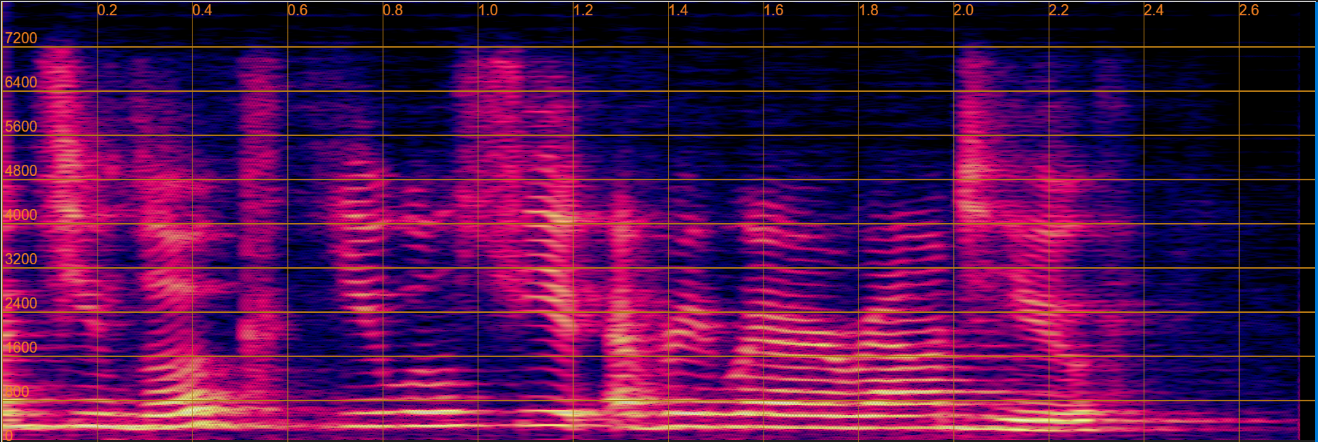 |
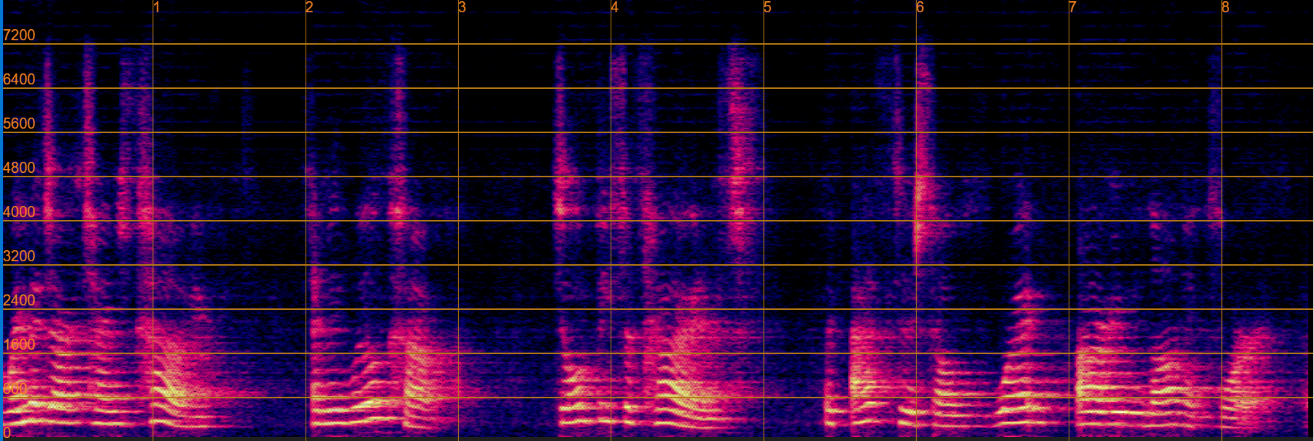 |
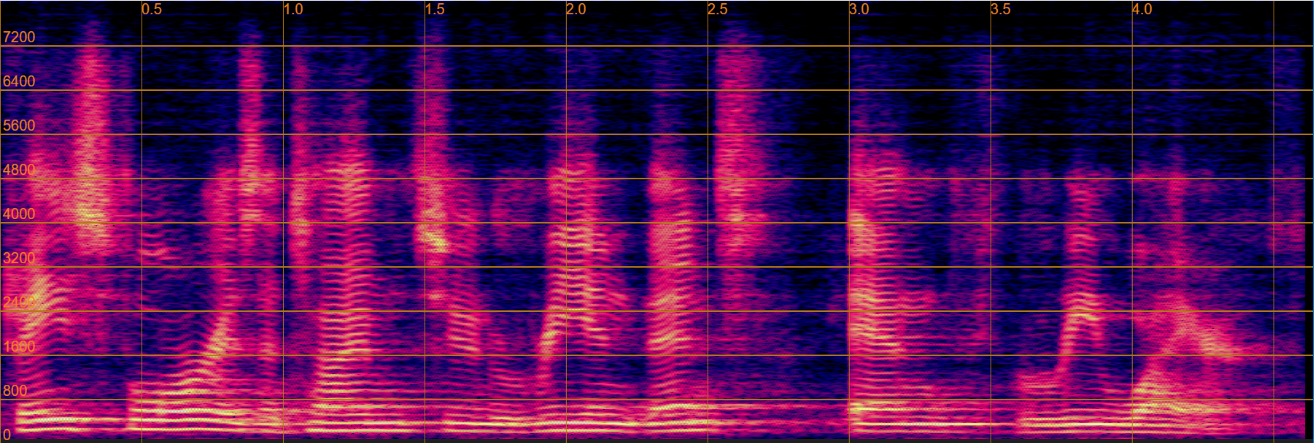 |
| (Audio) | |||
| Sep before Derev(joint) | 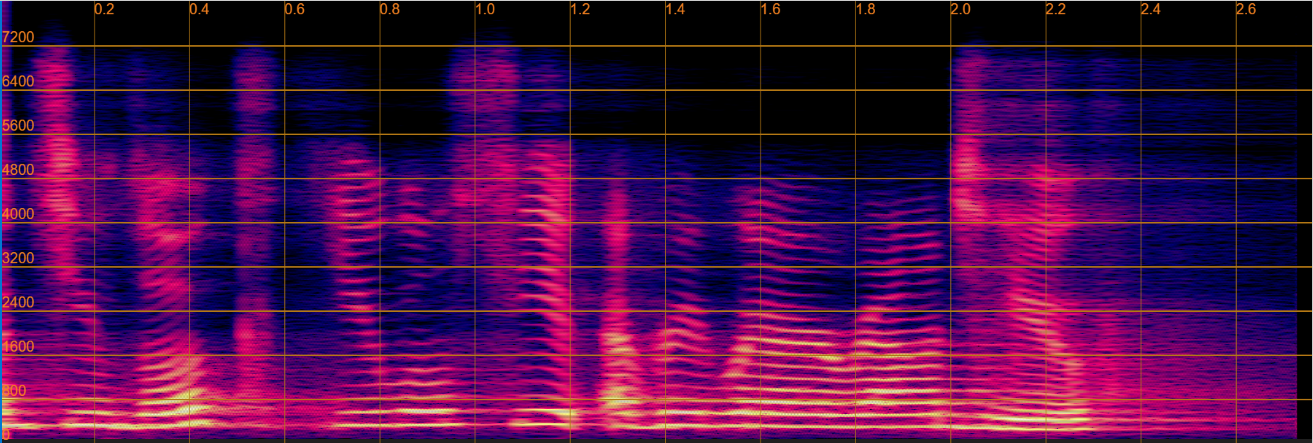 |
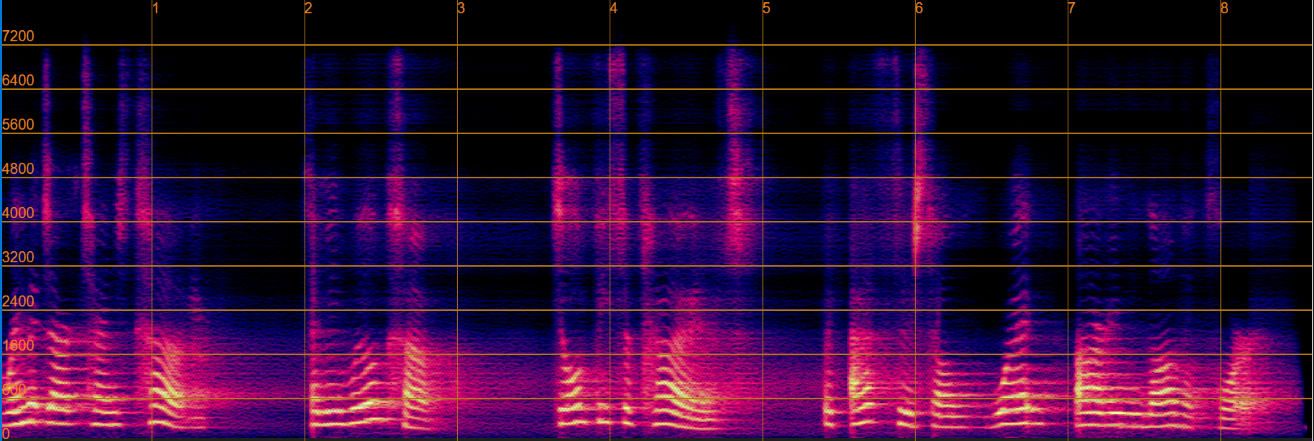 |
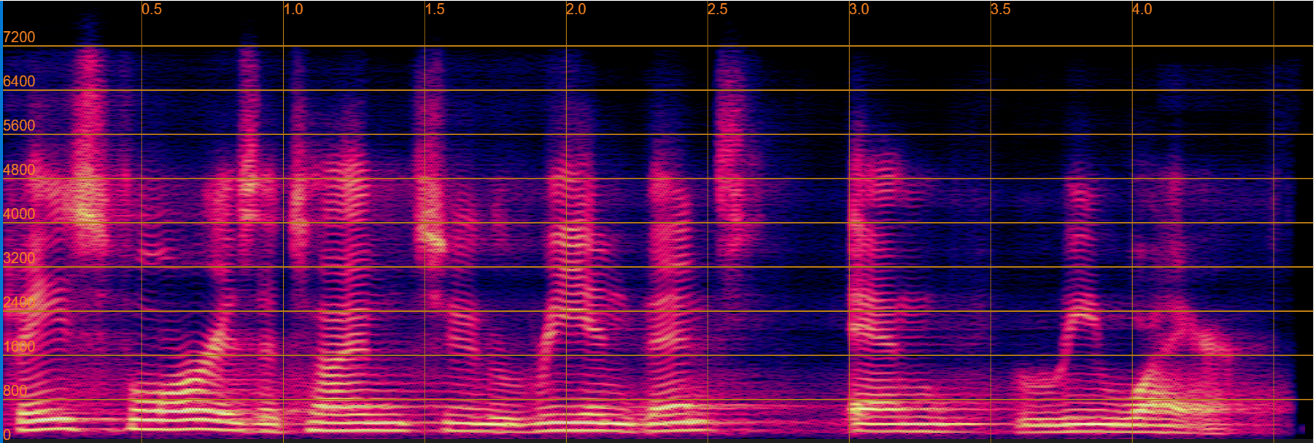 |
| (Audio) |